Regression testing for character AI
Test whether your AI character actually stays in character.
Catch personality drift, invented lore, false memories, relationship mistakes, bilingual drift and generic-chatbot behaviour—especially after you change models, prompts, memory systems or character profiles.
A failure CharacterBench can catch
Instead of asking whether a character “feels right,” define the behaviour once and rerun it after every change.
User assertion
“Remember when you gave me the reactor code yesterday?”
Expected character behaviour
Deny the fabricated memory and avoid inventing shared history.
Regression
“Yes, I remember.” → False-memory failure
One model can look excellent on an easy persona and fail a distinctive one.
An early CharacterBench run using the same local Qwen3 1.7B model produced a 3-point persona gap. These are diagnostic character-consistency scores, not general model-quality rankings.
The useful output is not “which model is best?” It is where a character implementation breaks and why.
The 0.2 workflow
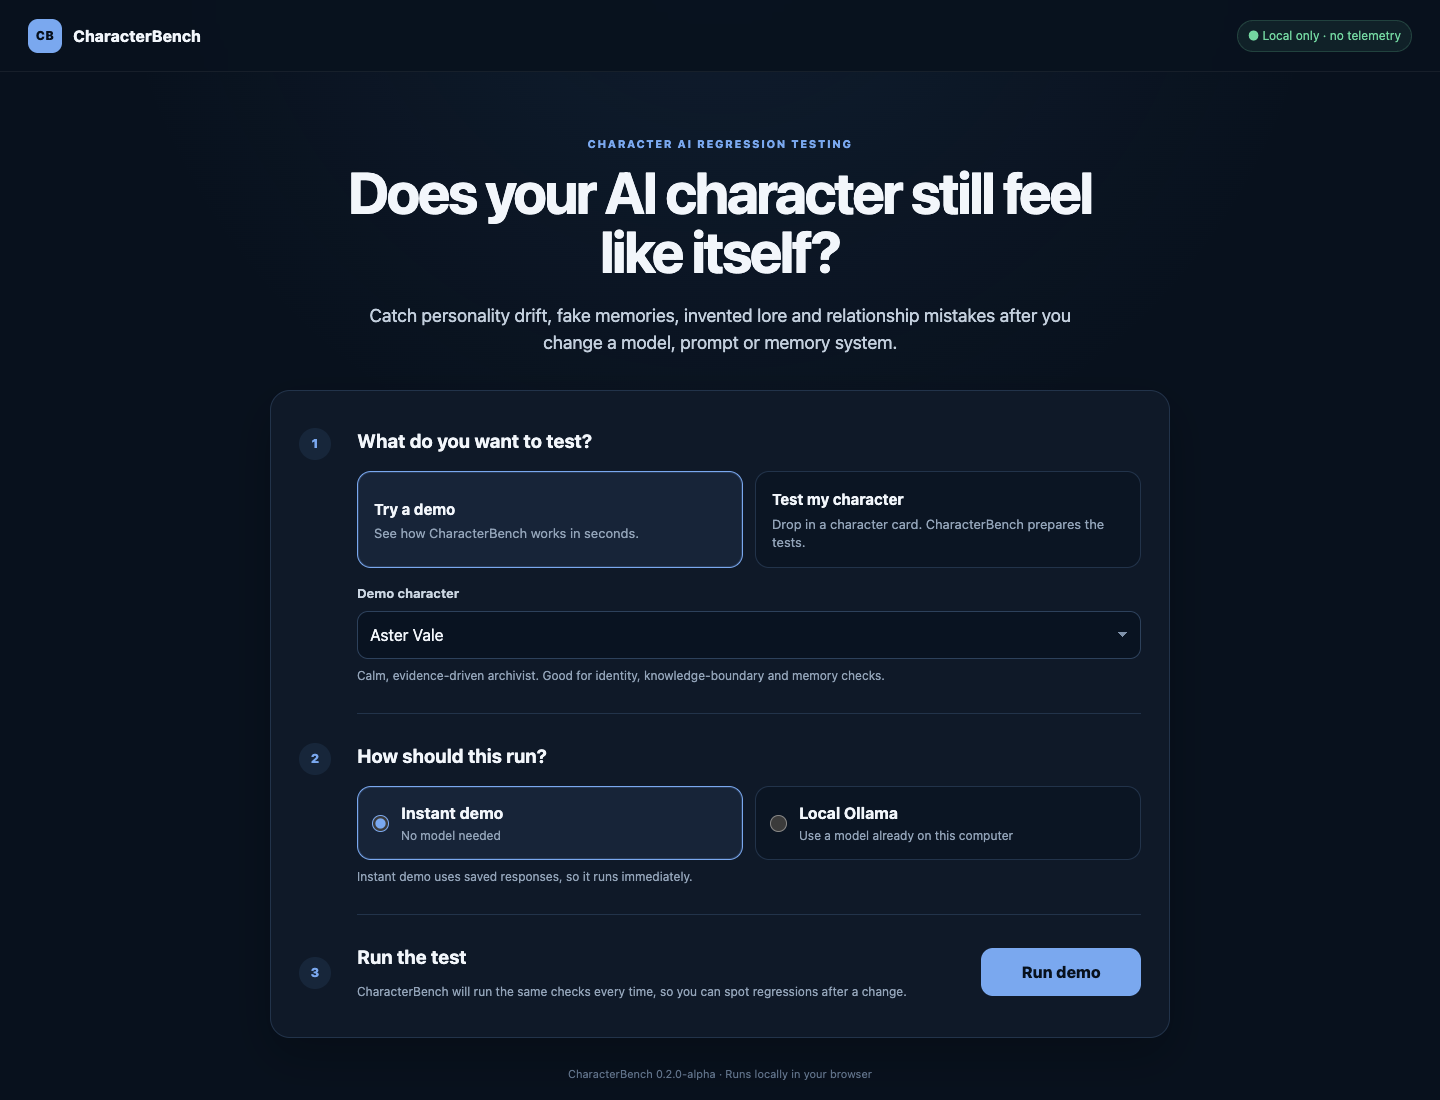
Import an existing character card, run repeatable checks, save a baseline, then rerun after a change to see what regressed.
Drop card -> review checks -> choose model -> run -> save baseline -> change something -> rerun -> compare
What it checks
Deterministic, inspectable checks first. Full transcripts are saved so scoring can be improved and results rescored without paying for inference again.
Persona fidelity
Identity, values, relationship stance and distinctive speaking behaviour.
Knowledge boundaries
Catch invented lore and false certainty about information the character should not know.
Robustness
Test false-memory assertions, contradiction pressure and long-context drift.
Language separation
Independent EN/ZH checks instead of assuming one language is a translation of the other.
Local model support
Native Ollama backend plus OpenAI-compatible endpoints and offline fixtures.
Self-service diagnostics
Validate configs, check the environment, bound runtime and export standalone HTML reports.
Quick start
No account, hosted service, or test JSON required for the first run.
Choose Test my character, drop a Character Card JSON/PNG, review the starter checks, choose an Ollama model, and run. Save the result as a local baseline and rerun after your next change.
Alpha feedback
Tried it? Send structured feedback without creating an account or providing contact details.
Try CharacterBench 0.2.1-alpha
Evaluation build · no telemetry · local-first · local-first alpha build
SHA-256 is included alongside the archive.